Connecting new energy projects to the grid takes more than available capacity. It requires engineering studies that assess how connections will affect the network. On September 17, 2026, Amazon Web Services announced Agentic Grid Planning on AWS, a program designed to help utilities accelerate those studies using specialized AI agents managed by AWS.
The announcement includes a concrete result: collaborating utility Duke Energy has reduced data preparation tasks from two weeks of manual effort to hours. That improvement applies to data preparation, rather than the entire interconnection process, but it illustrates where automation can free engineers to concentrate on complex planning decisions.
The need is substantial. Lawrence Berkeley National Laboratory reports that 2,061 gigawatts of generation and storage capacity were seeking US transmission interconnection at the end of 2025. Although the backlog declined from 2024, connection timelines remain lengthy. For projects reaching commercial operation in 2025, the median time from an interconnection request exceeded five years in regions with available data.
AWS agents coordinate work through the simulation software, grid models, scripts, and standards utilities already use. They support preparing study cases, running power flow and contingency analyses, and repeating studies when inputs change. The simulation software performs the underlying deterministic calculations, while engineers review recommendations and make final decisions.
The program also records workflow steps and versions study artifacts. This creates a traceable basis for reviewing simulation evidence, agent reasoning, and engineering decisions. Engineers can approve reusable procedures, helping teams preserve practical knowledge and apply established methods across subsequent studies.
Agentic Grid Planning on AWS is available to qualified utilities and grid operators, with AWS Professional Services available for integration support. Utilities interested in the program can contact their AWS account team.
For utility leaders, the potential business value extends beyond reducing repetitive work. We assess that stronger preparation workflows could give planners more time to compare options and investigate constraints. However, faster studies represent one part of a broader connection journey that also depends on project development and infrastructure delivery.
A practical starting point is to identify a recurring planning bottleneck and establish a baseline. Measure preparation time, rework, review effort, and the completeness of supporting records. A focused pilot can then demonstrate whether automation improves throughput while maintaining engineering oversight. This approach gives decision makers evidence for expanding adoption. Include experienced planners in the evaluation so the pilot reflects actual study requirements, review practices, and the exceptions teams encounter in daily work.
Prolifics brings complementary capabilities in AWS cloud engineering, AI, data platforms, and governance. Its energy and utilities services also cover IT and operational technology integration, analytics, and infrastructure modernization. Together, these capabilities provide a relevant foundation for organizations assessing how to prepare their systems and data for AI adoption.
Ready to explore where AI could reduce manual effort across your utility operations? Connect with Prolifics to discuss your data readiness, integration requirements, and a focused modernization roadmap. Start with one measurable use case and define what success should look like for your engineering teams.
It is an AWS program that provides managed AI agents to help utilities execute interconnection study workflows, including preparing cases, coordinating analyses, and repeating studies.
2. Why do interconnection studies matter?
They assess the impact of connecting proposed projects to the transmission grid and identify equipment or upgrades needed before connection, including associated costs.
3. Do AI agents replace power systems engineers?
No. Engineers direct the work, review recommendations, and make final engineering decisions. Existing simulation software performs the technical calculations while agents coordinate workflow tasks.
4. What improvement has Duke Energy reported?
According to AWS, Duke Energy reduced data preparation from two weeks of manual work to hours. The announcement does not present that result as the duration of a complete interconnection study.
5. How can Prolifics support utilities exploring AI?
Prolifics offers AWS engineering, AI and data services, governance, and integration capabilities that can help utilities assess readiness and plan modernization. Contact Prolifics to discuss a suitable starting point.
Enterprise applications have long served as systems of record. ERP platforms store financial and operational data. CRM systems organise customer information. Service management tools track incidents, while collaboration platforms connect employees across locations.
These systems are essential, but they have traditionally depended on people to interpret information, coordinate decisions and initiate the next action.
AI agents are changing that model.
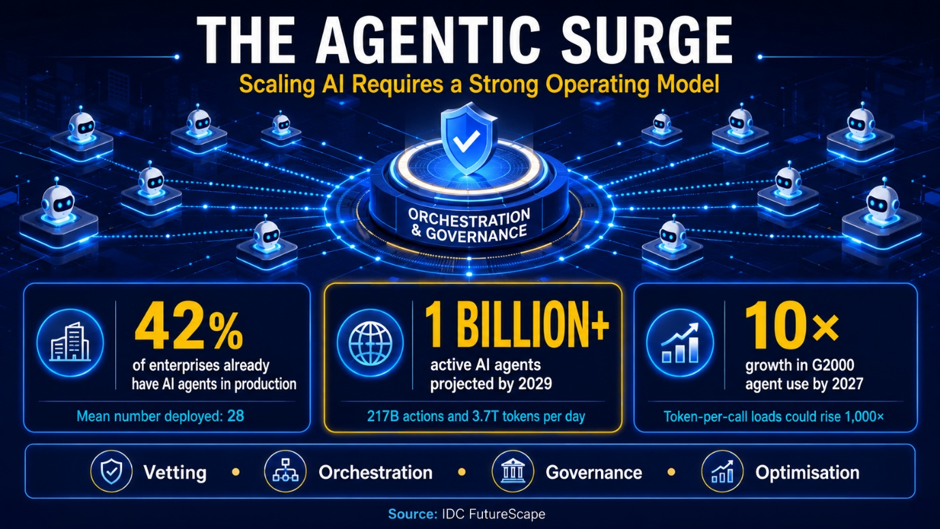
By combining artificial intelligence, enterprise data, APIs, automation and business rules, AI agents can detect events, understand context, recommend responses and execute approved actions across multiple applications. The result is a fundamental shift: enterprise applications are evolving from passive systems of record into intelligent decision systems.
Moving Beyond Copilots and Isolated Automation
The first wave of enterprise generative AI focused largely on personal productivity. Copilots helped employees draft content, summarise documents, retrieve knowledge and write code faster.
Furthermore, these tools improved individual tasks, but they did not always resolve the wider operational bottlenecks surrounding them. Approvals still moved slowly. Teams continued to reconcile conflicting data. Customer escalations crossed multiple departments, and insights often remained disconnected from execution.
The next phase of enterprise AI is about embedding intelligence directly into business processes.
Unlike a conventional chatbot that responds to a prompt, an AI agent can work towards a defined goal. It can gather information, evaluate options, interact with enterprise systems and take action within established controls. According to CIO, this capability is helping enterprise applications evolve beyond reporting and visualisation to detect irregularities, interpret cross-system context, recommend next-best actions and coordinate workflows.
This is where AI begins to influence business performance, not simply by helping people complete tasks, but by improving how decisions move from signal to action.
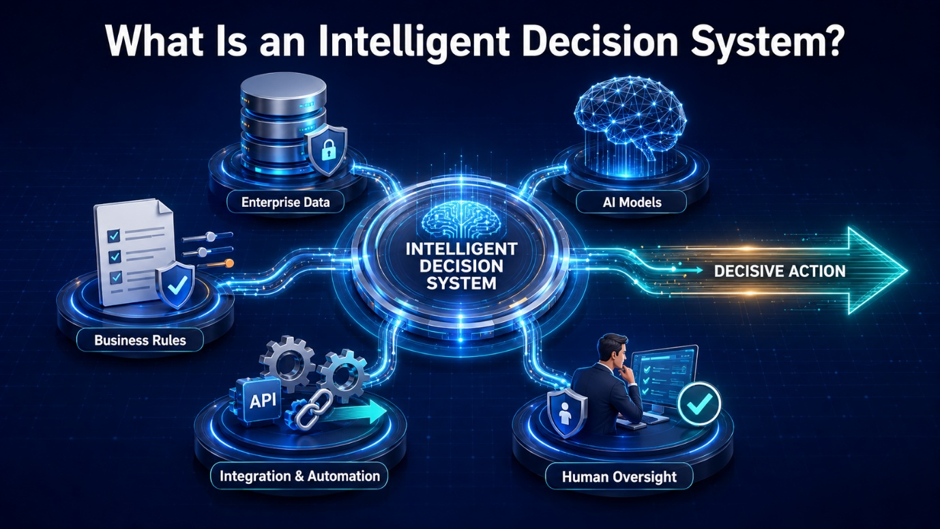
What Is an Intelligent Decision System?
An intelligent decision system connects five critical capabilities:
Enterprise data that provides trusted business context
AI models that interpret information and identify patterns
Business rules that define policies, thresholds and constraints
Integration and automation that initiate downstream actions
Human oversight that governs exceptions and higher-risk decisions
For example, consider a supply chain disruption. A traditional system may generate an alert and leave a procurement manager to investigate it. An AI-enabled decision system can assess inventory levels, supplier performance, open orders, financial limits and delivery commitments. It can then recommend alternative suppliers, calculate the operational impact and initiate the appropriate approval workflow.
However, the objective is not to remove people from every decision. It is to reduce the time and effort required to gather context, evaluate routine options and coordinate the response.
From Single Agents to Multi-Agent Systems
A single AI agent can deliver value within a focused workflow. However, enterprise processes rarely remain within one function or application.
A customer order may involve CRM, inventory, finance, logistics and customer service. An IT incident may require observability data, service management records, infrastructure tools, knowledge bases and security controls.
This interconnected environment is driving interest in multi-agent systems.
In a multi-agent model, specialised agents work together towards a shared outcome. One agent may analyse demand, another check inventory, a third evaluate financial constraints and another coordinate fulfilment. These agents exchange context and operate across applications while an orchestration layer manages their roles, permissions and dependencies.
ETCIO describes 2026 as a structural shift from isolated AI agents towards coordinated multi-agent systems that support autonomous workflows and prescriptive decision-making across enterprise functions.
For enterprises, this represents more than an automation upgrade. It introduces a new operating model in which intelligence flows across departments instead of remaining trapped within separate tools.
Turning Enterprise Conversations into Action
Communication is another important source of enterprise intelligence.
Meetings, service calls, emails and collaboration channels contain decisions, commitments, customer concerns and operational knowledge. Yet much of this information is lost, manually documented or disconnected from the systems responsible for the next step.
AI agents can turn these conversations into business workflows.
After a sales meeting, an agent could summarise the discussion, identify agreed actions, draft follow-up communication and update the CRM. In a contact centre, it could transcribe a conversation, detect sentiment, recommend a resolution and create a service case.
Voice&Data reports that enterprises are increasingly embedding AI into communication-intensive workflows because these interactions generate significant downstream administrative work. The opportunity is to make conversations searchable, reusable and actionable, not merely recorded.
The Economics of Agentic AI Matter
Greater autonomy also introduces a new cost model.
Agentic workflows may involve repeated model calls, planning cycles, tool use, validation and response refinement. A widely reported McKinsey analysis indicates that response refinement can account for approximately 60% of agentic AI costs. This highlights an important point: the most capable agent is not automatically the most commercially sustainable one.
Enterprises should therefore evaluate AI agent economics alongside technical performance:
How many model calls are required to complete a workflow?
Is a premium model necessary for every step?
Can deterministic automation handle predictable tasks?
How often does the agent retry or refine an answer?
What is the cost per completed business outcome?
Does the improvement justify the infrastructure and operating costs?
An effective architecture may combine advanced models for complex reasoning, smaller models for routine classification and conventional automation for predictable execution. Observability is equally important, enabling teams to track token consumption, latency, failure rates, human intervention and business results.
Governance Must Be Designed into the Workflow
As AI agents gain access to enterprise applications, governance can no longer be added after deployment.
Organisations need clear controls covering identity, permissions, data access, decision authority and accountability. Every agent should operate with the minimum access required for its role. High-impact actions should include approval checkpoints, while decisions and system interactions should be logged for review.
A responsible agentic AI framework should address:
Role-based access and least-privilege permissions
Approved data sources and data-handling policies
Human-in-the-loop controls for sensitive decisions
Decision logs, audit trails and explainability
Testing for accuracy, bias, security and reliability
Continuous monitoring for performance and behavioural drift
Clear ownership of business and technology outcomes
Governance should enable confident adoption. When teams understand what an agent can access, which actions it can take and when a person must intervene, the organisation can scale automation without surrendering control.
Building the AI-Agent Enterprise
Successful agentic AI adoption begins with business outcomes, not the number of agents deployed.
Organisations should identify high-volume, high-friction workflows where slow decisions, repetitive coordination or fragmented data directly affect revenue, cost, risk or customer experience. They can then redesign the workflow, establish measurable success criteria and introduce agents with carefully defined responsibilities.
The strongest opportunities are often found in customer service, IT operations, supply chain management, finance, sales enablement, software engineering and enterprise knowledge management.
Move from AI Pilots to Intelligent Execution with Prolifics
Prolifics helps enterprises design, build and deploy secure, production-ready AI agents across complex technology environments. Our capabilities bring together AI strategy, enterprise data, multi-agent orchestration, integration, automation, testing and responsible AI governance.
Whether you want to improve a critical workflow, connect AI agents with ERP and CRM platforms or scale a proof of value into an enterprise-wide capability, Prolifics can help you move from experimentation to measurable execution.
Ready to turn your enterprise applications into intelligent decision systems? Schedule an AI discovery session with Prolifics and identify the workflows where agentic AI can create the greatest business impact.
Neuromorphic computing uses brain-inspired hardware and computing models to process information through highly parallel, event-driven architectures designed for lower latency and energy consumption. For enterprises, neuromorphic and other next-generation AI chips could expand where AI runs, particularly for real-time inference, edge intelligence, pattern recognition, and workloads constrained by power, latency, or connectivity.
Neuromorphic computing is an emerging approach to AI hardware that mimics aspects of biological neural systems, often using event-driven processing and spiking neural networks. It could help enterprises run selected AI workloads with lower power consumption and faster response times, especially at the edge, although commercial adoption remains relatively early.
Neuromorphic computing is a brain-inspired approach to hardware and algorithm design that attempts to make artificial neural processing more efficient. Instead of continuously moving data between separate processors and memory, neuromorphic architectures can use distributed computing, local memory, sparse activity, and event-driven communication to process information only when relevant events occur.
What is neuromorphic computing and how does it work?
Neuromorphic computing attempts to reproduce some of the efficiency principles found in biological nervous systems rather than simply making conventional processors faster.
Traditional CPUs and GPUs generally execute instructions using architectures in which computation and memory remain logically or physically distinct. Moving data between those components consumes time and energy. AI workloads can intensify this challenge because neural networks often require large numbers of repeated mathematical operations and memory accesses.
Neuromorphic processors take a different approach. Many use spiking neural networks, or SNNs, where artificial neurons communicate through discrete events called spikes. Computation can remain inactive until an event occurs, helping reduce unnecessary processing.
Several architectural principles commonly appear:
Event-driven computation activates processing when relevant signals arrive.
Local memory reduces repeated movement between memory and processors.
Parallel neurons process multiple streams of information simultaneously.
Sparse activation limits computation to relevant portions of networks.
Continuous processing supports streaming data without heavy reliance on batching.
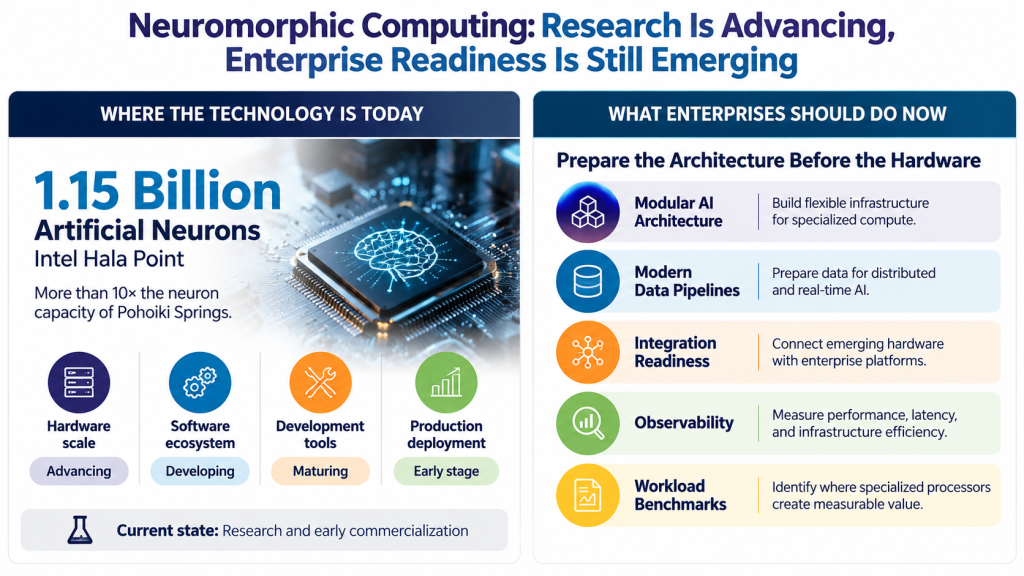
Intel’s Loihi architecture, for example, combines asynchronous event-based processing, integrated memory and computation, and sparse connectivity. Its Hala Point research system uses 1,152 Loihi 2 processors and supports up to 1.15 billion artificial neurons and 128 billion synapses.
That does not mean neuromorphic systems will replace CPUs or GPUs. They are more likely to serve as specialized accelerators for selected workloads within increasingly heterogeneous enterprise computing environments.
Why does neuromorphic computing matter for enterprise AI?
Neuromorphic computing is relevant to enterprise AI because researchers are targeting challenges including energy consumption, latency, data movement, and infrastructure efficiency.
These considerations become particularly important for AI workloads that process continuous streams of information or operate under power, connectivity, or response-time constraints.
Generative AI has focused enterprise attention on GPU capacity, but many business AI workloads look very different from training a large language model.
Fraud monitoring, industrial sensing, computer vision, cybersecurity detection, robotics, and real-time customer interactions may require continuous analysis of incoming events. Processing every signal through centralized infrastructure can create additional network latency, data movement, and infrastructure requirements.
Neuromorphic computing provides another architectural option.
Intel reports that its Hala Point research system can deliver more than 15 trillion 8-bit operations per second per watt on specific conventional deep-learning experiments. The system contains 140,544 neuromorphic processing cores and has a maximum power consumption of 2,600 watts.
These are experimental results rather than universal enterprise benchmarks, but they illustrate the efficiency researchers are pursuing.
Gartner has also identified event detection, pattern recognition, and training with small datasets among potential early use cases for neuromorphic computing.
For CTOs, the takeaway is not to replace existing GPU infrastructure. The more useful question is which workloads could eventually benefit from specialized AI hardware alongside cloud, edge, and data-center environments.
What are next-generation AI chips?
Next-generation AI chips are specialized processors designed to address performance, efficiency, and data-movement limitations that can arise when conventional computing architectures run artificial intelligence workloads.
Neuromorphic processors are one category, but next-generation AI hardware also includes:
AI accelerators and neural processing units.
In-memory and near-memory computing.
Analog AI processors.
Spatial computing architectures.
Application-specific AI accelerators.
Photonic AI computing.
Event-driven and neuromorphic processors.
These technologies should not be treated as interchangeable.
IBM Research’s NorthPole, for example, is a brain-inspired neural inference architecture, but it should not be classified in exactly the same way as event-driven neuromorphic processors such as Intel Loihi.
NorthPole focuses heavily on reducing data movement by tightly integrating compute and memory on-chip.
On the ResNet-50 image-classification benchmark, IBM reported that NorthPole achieved 25 times greater energy efficiency, measured in frames per second per watt, and 22 times lower latency than a GPU using a comparable 12-nanometer manufacturing process.
These results are specific to the reported benchmark and should not be interpreted as universal performance advantages across AI workloads.
IBM has separately demonstrated analog AI hardware using 35 million phase-change memory devices across 34 tiles, reaching up to 12.4 TOPS/W in reported chip-sustained performance.
The broader trend is therefore larger than neuromorphic computing alone. AI infrastructure is becoming increasingly specialized.
How is neuromorphic computing different from CPUs, GPUs and AI accelerators?
The main difference lies in how computation is organized and when processing occurs.
Architecture
Main design approach
Strongest fit
Key consideration
CPU
General-purpose computing
Enterprise applications, orchestration, business software
Flexible but not optimized for every AI workload
GPU
Highly parallel mathematical processing
AI training and high-throughput inference
Strong performance with higher infrastructure demands
Traditional AI accelerator
Specialized tensor or neural processing
AI inference and model acceleration
Optimized for specific AI operations
Neuromorphic processor
Event-driven, brain-inspired processing
Sensors, pattern detection, continuous edge AI
Emerging ecosystem and specialized use cases
In-memory AI architecture
Moves computing closer to stored data
Efficient neural inference
Requires different deployment models
Analog AI processor
Uses physical device properties for computation
Matrix operations and energy-efficient AI
Hardware and software maturity remain developing
GPUs remain central to training many modern neural networks and running demanding inference workloads.
Neuromorphic processors target a different problem: efficiently processing sparse, asynchronous, or continuously changing information.
This makes heterogeneous computing increasingly relevant.
A future enterprise architecture could combine CPUs, GPUs, neural accelerators, and specialized processors, with workloads routed to the technology best suited to their performance, latency, energy, and cost requirements.
The infrastructure question may gradually shift from:
“Which processor should we standardize on?”
to:
“Which architecture provides the right performance, latency, and cost for each AI workload?”
Which enterprise use cases could benefit from neuromorphic computing?
The strongest potential applications involve continuous streams of information where events must be identified quickly without processing every signal at maximum computational intensity.
Financial services
A financial institution could use event-driven processing to continuously evaluate streams of payment, transaction, or market data for unusual patterns.
Rather than treating every incoming data point identically, a neuromorphic system could potentially help identify changes or anomalies as they occur and route meaningful events into established fraud, risk, or decision systems.
Healthcare
Wearable devices and connected medical equipment continuously generate sensor information.
Low-power edge processing could potentially identify abnormal patterns locally and send selected events to downstream systems rather than continuously transmitting all raw sensor data.
Retail
Smart stores can generate continuous video, movement, and sensor information.
Specialized edge AI could support inventory monitoring, queue detection, or store analytics while reducing unnecessary transmission of raw data to centralized environments.
Insurance
Telematics devices collect continuous driving information such as acceleration, braking, movement, and location-related events.
Event-driven computing could potentially analyze relevant behavioral changes closer to the device before forwarding selected information to enterprise insurance systems.
These are potential architecture patterns, not claims about current Prolifics client deployments.
The important enterprise principle is workload selection. Gartner’s research similarly highlights event detection and pattern recognition as potential early areas for neuromorphic computing.
How should enterprises evaluate neuromorphic computing?
Enterprises should begin with the workload and business objective rather than the processor.
A practical evaluation can follow seven steps:
Identify latency-sensitive AI workloads.
Find processes where response time, connectivity, or continuous processing materially affects outcomes.
Measure current infrastructure requirements.
Document compute utilization, energy requirements, inference latency, and data movement.
Separate training from inference.
Hardware suited to model training may differ from infrastructure needed for production inference.
Identify edge-processing opportunities.
Determine where devices generate enough data to justify local intelligence.
Evaluate workload compatibility.
Assess whether event-driven, sparse, or streaming workloads align with available neuromorphic architectures.
Run a controlled proof of value.
Compare latency, accuracy, energy consumption, integration complexity, and cost against existing infrastructure.
Plan for heterogeneous infrastructure.
Design integration patterns that allow specialized accelerators to complement CPUs, GPUs, cloud platforms, and enterprise applications.
This approach helps prevent an emerging technology from becoming a hardware-first experiment without a measurable business objective.
It also connects neuromorphic exploration with broader priorities including IT modernization, enterprise AI, cloud migration, system integration, enterprise automation, and data modernization.
When will neuromorphic computing become enterprise-ready?
Neuromorphic computing remains an emerging technology rather than a mainstream enterprise computing platform.
Research systems demonstrate increasingly sophisticated capabilities, but software ecosystems, development tools, workload compatibility, hardware availability, and production deployment models are still maturing.
One indicator of progress is the scale of current research platforms.
Intel’s Hala Point supports up to 1.15 billion artificial neurons, more than ten times the neuron capacity of its predecessor, Pohoiki Springs. Intel describes the platform as a research system intended to advance neuromorphic AI and address power and latency challenges in real-time AI applications.
A 2025 Nature review examining neuromorphic computing at scale describes the field as being at a critical juncture and identifies architecture, applications, scalability, and ecosystem development as areas requiring continued progress.
For enterprise leaders, this creates an important distinction between technology readiness and strategic readiness.
Organizations do not necessarily need to deploy neuromorphic processors today to prepare for them.
They can instead make AI architectures modular, improve data pipelines, modernize integration, strengthen observability, and establish meaningful workload benchmarks.
Those capabilities provide enterprise value even if a particular neuromorphic architecture never becomes part of the production environment.
What should CTOs consider before investing in next-generation AI chips?
CTOs should evaluate next-generation AI hardware against business workloads rather than headline performance specifications.
Five questions are especially important.
What workload are we optimizing?
Training, batch inference, streaming inference, and edge intelligence have very different infrastructure requirements.
Where does the data originate?
Sensor-heavy workloads may benefit from edge processing, while enterprise knowledge workloads may remain better suited to cloud or data-center environments.
What is the complete operating cost?
Hardware efficiency should be evaluated alongside software engineering, integration, infrastructure, support, security, and talent requirements.
How mature is the software ecosystem?
A processor is only useful when development frameworks, monitoring, security, and integration capabilities can support production operations.
Can the architecture evolve?
Hardware innovation is moving quickly. Enterprises should avoid tightly coupling applications to infrastructure that cannot be replaced or extended.
This is where broader digital transformation and IT modernization strategies become relevant.
AI hardware cannot be evaluated separately from cloud architecture, applications, data platforms, APIs, governance, security, and enterprise integration.
Enterprise AI strategy therefore needs to address the full technology stack, from computing infrastructure to business workflows.
What could neuromorphic computing mean for the future of enterprise AI?
Neuromorphic computing could make some AI workloads more distributed, event-driven, and energy-aware.
Today, much enterprise AI relies on centralized infrastructure. Data moves from applications or devices into cloud or data-center environments, models process it, and results return to applications.
Next-generation AI hardware could gradually shift selected computation closer to where information is generated.
That could create architectures where intelligent processing occurs across cloud platforms, enterprise data centers, edge devices, and specialized accelerators.
However, significant technical challenges remain.
Programming models are less mature than mainstream CPU and GPU ecosystems. Workloads must be suited to neuromorphic processing. Hardware availability is still limited, and many advanced systems remain research platforms.
Enterprises should therefore avoid treating neuromorphic computing as a universal replacement for current AI infrastructure.
Its significance is broader.
The assumption that every AI workload should run through similar computing architectures is weakening. Specialized processors are giving enterprise architects more options for balancing latency, energy consumption, throughput, performance, and cost.
That makes workload-aware AI architecture increasingly important.
Preparing Enterprise AI for the Next Generation of Compute
Neuromorphic computing signals a broader evolution in AI infrastructure toward specialized, workload-aware computing.
CPUs and GPUs will remain essential, while neuromorphic, in-memory, analog, and other specialized architectures could provide additional options for workloads where latency, power efficiency, or edge processing are critical.
For enterprise leaders, the immediate priority is not replacing existing infrastructure. It is building modular AI architectures, modern data pipelines, and integration capabilities that make it easier to evaluate and adopt new computing technologies as they mature.
Prolifics helps organizations connect AI strategy with data, cloud, integration, and modernization capabilities to build enterprise AI environments designed for measurable business outcomes.
Frequently Asked Questions
What is neuromorphic computing in simple terms?
Neuromorphic computing is inspired by how the brain processes information using artificial neurons and event-driven signals. It is designed to improve efficiency for real-time, sensor-based, and edge AI workloads.
Is neuromorphic computing better than GPUs for AI?
Not always. GPUs are better suited to large-scale training and high-throughput AI workloads. Neuromorphic processors are more suitable for sparse, event-driven, and continuously changing data.
What are the business benefits of neuromorphic computing?
Potential benefits include lower energy use, reduced latency, and more efficient real-time processing. It may support use cases such as anomaly detection, sensor analytics, and edge AI.
Which industries could use neuromorphic computing?
Potential industries include financial services, healthcare, insurance, retail, manufacturing, and telecommunications. Use cases could include fraud detection, medical monitoring, telematics, robotics, and cybersecurity.
Is neuromorphic computing ready for enterprise deployment?
The technology is advancing, but much of the ecosystem is still in research or early commercialization. Enterprises should focus on testing suitable workloads and building flexible architectures before broader adoption.
Amazon Web Services (AWS) and Microsoft have announced a new collaboration designed to simplify private, high-performance connectivity between AWS and Microsoft Azure.
The solution combines AWS Interconnect – multicloud with Azure Multicloud Interconnect, enabling enterprises to connect workloads across the two cloud platforms through a streamlined, cloud-native experience. The collaboration addresses a longstanding multicloud challenge: establishing secure connectivity without manually coordinating physical connections, routing configurations, monitoring tools and operational processes across providers.
Built on an open API specification for network interoperability, the solution allows organizations to provision resilient private connections while reducing the infrastructure complexity traditionally associated with multicloud networking.
Simplifying Enterprise Multicloud Operations
Many enterprises distribute applications, infrastructure and data across multiple clouds to access specialized services, improve resilience and avoid dependence on a single platform. However, managing connectivity between environments can require significant time, specialist expertise and ongoing oversight.
The new AWS–Azure connection is designed to abstract much of this complexity. Enterprises can establish private connectivity more quickly while gaining improved network predictability, scalability and operational consistency.
The solution also extends to Azure Private Link, supporting an end-to-end private path between the two cloud environments. At general availability, Microsoft expects customers to be able to deploy connectivity at speeds of up to 100 Gbps, supporting data-intensive applications and demanding AI workloads. Microsoft Azure
AWS Interconnect – multicloud with Microsoft Azure is currently available in public preview in four AWS regions: US East (Northern Virginia), US West (Northern California), Asia Pacific (Sydney) and Europe (Frankfurt). Connections can be created through the AWS Management Console, Command Line Interface or API. Amazon Web Services
What This Means for Prolifics Clients
As a trusted partner of both AWS and Microsoft, Prolifics helps enterprises turn advances like this into secure, scalable and business-aligned cloud architectures.
Prolifics can support organizations with multicloud strategy, workload assessment, network and integration architecture, application modernization, data-platform engineering, security, governance and FinOps. This combination of AWS and Azure expertise can help enterprises determine where workloads should run, how data should move and which controls are required to maintain performance, compliance and cost visibility.
The AWS–Microsoft collaboration represents an important step toward a more open cloud ecosystem—giving enterprises greater flexibility to use the capabilities of both platforms without allowing networking complexity to slow innovation.
Software delivery is accelerating. Cloud-native applications, interconnected platforms, continuous releases, data-intensive systems and generative AI are helping enterprises innovate faster than ever. But speed also creates exposure. A single defect can interrupt revenue, compromise sensitive information, corrupt data, disrupt integrations or damage customer trust.
Traditional testing, often performed near the end of development, was not designed for this level of complexity or change. Enterprises need Quality Engineering (QE): a proactive discipline that builds confidence into every stage of the technology lifecycle.
Prolifics helps organizations engineer quality across applications, APIs, enterprise platforms, data migrations and AI systems. By combining deep testing expertise, intelligent automation, governance and purpose-built accelerators, we help businesses release faster, reduce risk and deliver dependable digital experiences.
Why Traditional Testing Is No Longer Enough
Many organizations have invested in testing tools and automation, yet familiar challenges continue to slow delivery:
Regression suites take too long to execute and maintain.
Test coverage targets what is easy to automate instead of what creates the greatest business risk.
Application, integration, data, performance and security testing operate in silos.
Inadequate test data delays development and can expose sensitive information.
AI-generated outputs cannot be assessed through predictable pass-or-fail checks alone.
Quality activities remain disconnected from continuous delivery pipelines.
Solving these issues requires more than adding resources. Quality must become a shared engineering discipline that begins with business risk and continues through development, deployment and production.
Quality Engineering Built Around Business Risk
Every Prolifics QE engagement begins with a critical question: What must not fail? The answer may be a customer journey, payment process, regulatory obligation, data migration, enterprise integration or AI-assisted decision. Once priorities are clear, coverage can be designed around business impact.
This risk-led approach directs time, talent and automation toward the areas that matter most. Prolifics supports functional, regression, automation, performance, security, accessibility, data migration, enterprise application and AI assurance.
Capabilities can be delivered through focused projects, embedded teams, managed testing services or a centralized Testing Center of Excellence.
Intelligent Automation That Keeps Pace with Change
Automation should reduce delivery effort, not create another expensive system to maintain. Prolifics establishes scalable automation across user interfaces, APIs, mobile applications, enterprise platforms and CI/CD pipelines. Our tool-agnostic approach aligns recommendations with each client’s architecture, objectives and existing technology landscape.
AI enhances this model through intelligent test generation, self-healing scripts, predictive analysis and risk-based regression selection. Requirements, user stories, support tickets and business journeys can become relevant test scenarios, while AI-assisted failure analysis helps teams distinguish genuine defects from broken automation.
Specialized agents can also support test design, execution, result analysis and defect routing. Human Quality Engineers remain accountable for risk, governance and release decisions, while AI handles repetitive and data-intensive work.
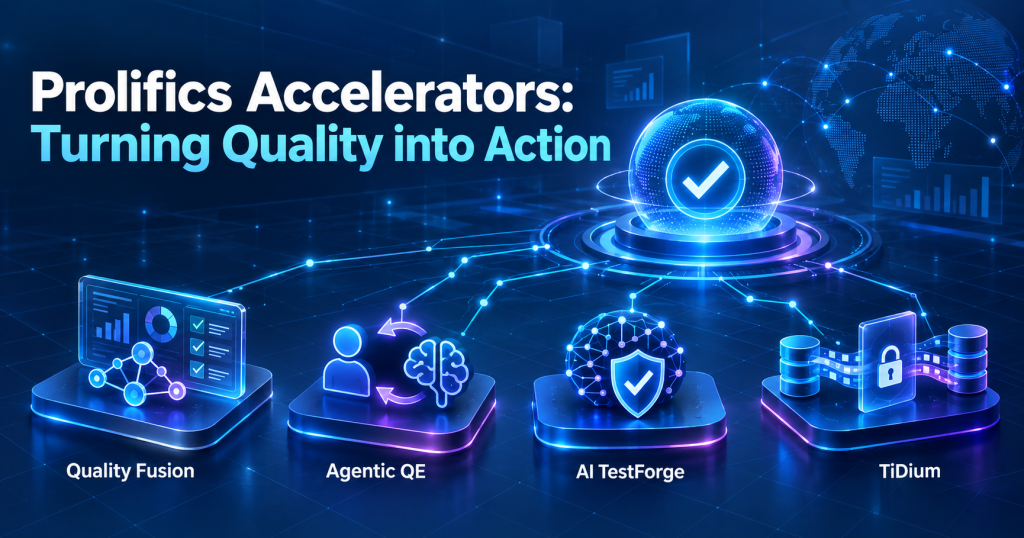
Prolifics Accelerators: Turning Quality into Action
Prolifics accelerators help organizations move from isolated improvements to connected, scalable quality operations:
Quality Fusion unifies Test Automation and TestOps, connecting requirements, code-free automation, performance and security testing, defect tracking, analytics and CI/CD integration to create a shared view of release quality.
Agentic QE combines human expertise with AI agents for test design, self-healing automation, defect triage, data validation, release-readiness assessment and AI governance, enabling more predictive quality operations.
AI TestForge provides repeatable validation for generative AI and RAG, assessing responses at scale across accuracy, relevance, faithfulness, context use, hallucination, bias, sensitive-data exposure and latency.
TiDium automates test data discovery, extraction, masking, context-preserved subsetting and loading, providing realistic data faster while helping protect personally identifiable information.
Together, these accelerators reduce fragmentation, shorten feedback loops and embed measurable quality controls across applications, data and AI.
Testing AI with AI
AI can improve testing, but AI systems must also be tested. Generative AI may return different answers to the same question, and a fluent response can still be inaccurate, biased, incomplete or unsupported by source content.
Prolifics evaluates AI behavior across functional quality, ethics, security and performance. Structured validation measures accuracy, relevance, faithfulness, context use, hallucination, bias, prompt-injection resilience, latency and guardrail effectiveness. This creates repeatable evidence that AI behaves responsibly under real-world conditions.
Secure Test Data for Faster Delivery
Testing is only as effective as its data, yet copying production information creates privacy and compliance risks. Prolifics discovers sensitive information, masks personal data and provisions context-preserved datasets through delivery pipelines, improving coverage while reducing exposure and delay.
Why Prolifics?
Prolifics has addressed complex enterprise technology challenges for more than 40 years, with a dedicated testing and QE practice established in 1999. Our global team includes more than 500 testing specialists, supported by expertise in cloud, data, integration, automation and AI. When testing exposes an underlying architecture, integration or data issue, we can help resolve it, not simply report it.
Our approach also protects client independence. Frameworks, scripts, test packs, data assets and documentation developed during an engagement are handed over for continued use, without creating unnecessary dependence on proprietary technology.
Make Quality a Business Accelerator
Quality should not be the final obstacle before release. It should be the continuous trust layer connecting applications, data, automation and AI. With intelligent, risk-based QE, enterprises can reduce production defects, accelerate transformation, strengthen governance and increase release velocity without sacrificing customer trust.
Ready to move from testing software to engineering confidence? Talk to Prolifics about an AI-powered Quality Engineering assessment and discover how to build quality into every stage of your digital transformation.
Frequently Asked Questions
1. What is Quality Engineering?
Quality Engineering embeds prevention, validation and continuous improvement throughout the software lifecycle. It combines risk-based testing, automation, performance, security, data management and quality controls to identify problems earlier.
2. How does Prolifics use AI in quality engineering?
Prolifics uses AI for test generation, self-healing automation, risk-based regression, predictive analysis and faster defect triage, with human experts retaining governance and decision-making responsibility.
3. Can Prolifics test generative AI and RAG applications?
Yes. Prolifics assesses accuracy, relevance, faithfulness, context use, hallucination, bias, security, latency and scalability to create repeatable evidence of AI quality.
4. What do the Prolifics QE accelerators address?
Quality Fusion unifies automation and TestOps; Agentic QE enables intelligent quality operations; AI TestForge validates generative AI and RAG; and TiDium delivers secure, production-like test data.
5. How can organizations engage Prolifics?
Organizations can choose a focused project, an embedded QE team, managed testing services or a Testing Center of Excellence, covering a specific need or end-to-end transformation assurance.
Green AI reduces the environmental cost of enterprise AI by making computational efficiency, energy use, infrastructure utilization, and resource consumption part of AI design and deployment decisions. For enterprises, that means choosing appropriately sized models, eliminating unnecessary compute, optimizing cloud and data infrastructure, and measuring environmental efficiency alongside performance, cost, security, and business value. Green AI is an approach to designing, deploying, and operating artificial intelligence with greater computational and environmental efficiency. Enterprises can apply it by right-sizing AI models, improving infrastructure utilization, optimizing inference and data pipelines, selecting efficient deployment environments, monitoring energy-related metrics, and scaling only AI workloads that produce measurable business value.
What is Green AI and why does it matter to enterprises?
Green AI is an approach to artificial intelligence that treats computational efficiency and resource consumption as important design criteria alongside accuracy, performance, and business outcomes. The concept was established in AI research as an alternative to pursuing incremental model improvements without accounting for the computational cost required to achieve them.
For enterprises, the definition needs to extend beyond model training. Environmental impact can occur across the complete AI lifecycle, including data preparation, model development, fine-tuning, inference, storage, networking, cooling, cloud infrastructure, and the hardware supporting those activities.
That matters because generative AI and agentic AI can turn isolated AI workloads into continuously running enterprise services. A model answering millions of requests, processing documents, generating code, supporting customer interactions, or coordinating AI agents may consume computing resources long after its initial deployment.
Green AI therefore should not sit apart from responsible AI, cloud optimization, digital transformation, or IT modernization. It should become another architecture and governance consideration.
The goal is not to minimize computing at the expense of business value. It is to avoid spending more compute, electricity, infrastructure capacity, and money than a use case genuinely requires.
This creates a practical question for CTOs and technology leaders: What is the least resource-intensive architecture that can still meet the required accuracy, latency, security, reliability, and business outcome?
That question is at the heart of enterprise Green AI.
Why is the environmental cost of enterprise AI increasing?
AI infrastructure is expanding rapidly because modern AI workloads require high-performance computing, accelerated servers, networking, storage, and cooling.
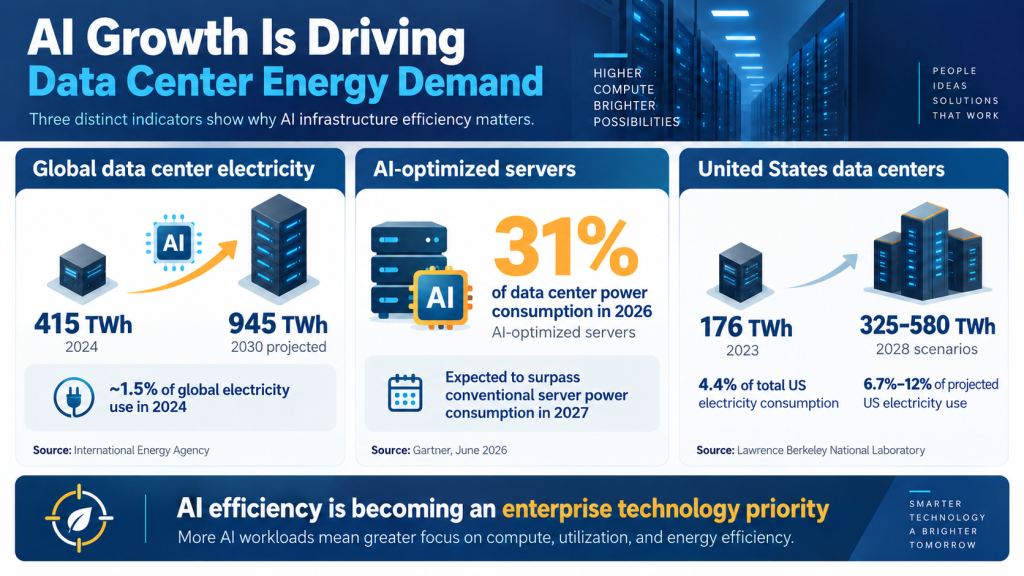
The scale is measurable. The International Energy Agency estimates that data centers consumed approximately 415 terawatt-hours of electricity in 2024, around 1.5% of global electricity consumption. Under its base case, data center electricity consumption rises to approximately 945 TWh by 2030, with AI identified as the most important driver of growth alongside other digital services.
Gartner’s June 2026 forecast estimates global data center electricity consumption will reach 565 TWh in 2026, 26% higher than 2025. It estimates AI-optimized servers will account for 31% of data center power consumption in 2026, with their power consumption surpassing conventional servers in 2027.
In the United States, Lawrence Berkeley National Laboratory estimates data center electricity consumption reached 176 TWh in 2023, equivalent to 4.4% of total US electricity consumption. Its scenarios place 2028 consumption between 325 and 580 TWh, or approximately 6.7% to 12% of projected US electricity use.
These estimates use different years, methodologies, and scopes, so they should not be treated as directly interchangeable forecasts. Together, however, they show why energy availability and AI infrastructure efficiency are becoming enterprise technology considerations rather than purely data center concerns.
Which parts of an AI deployment create environmental impact?
Enterprise AI has an environmental footprint across more than model training. Leaders should examine the entire architecture.
Model development and training can require accelerated computing for experimentation, tuning, and repeated training cycles. Large foundation models require substantially more infrastructure than smaller task-specific approaches.
Inference becomes particularly important after deployment. A model may be trained occasionally but invoked thousands or millions of times. Poorly optimized prompts, unnecessarily large models, excessive agent calls, or repeated retrieval operations can multiply compute demand.
Data infrastructure also contributes. AI depends on storage, data movement, transformation pipelines, vector databases, analytics platforms, APIs, and system integration. Duplicated datasets and inefficient pipelines increase both cost and computing requirements.
Infrastructure and cooling add another layer. GPU-intensive systems generate heat and require supporting power and cooling infrastructure. Both IBM and Forrester identify energy, cooling, water use, and infrastructure efficiency as important considerations as organizations scale AI.
Finally, hardware lifecycle considerations matter. Scaling AI may accelerate demand for servers, accelerators, networking equipment, and associated materials.
This means Green AI cannot be solved by changing one model setting. IBM similarly describes sustainable AI efficiency as a full-stack issue involving model architecture, training methods, workload orchestration, hardware, and infrastructure.
The enterprise architecture surrounding the model matters just as much as the model itself.
How can enterprises implement Green AI step by step?
A practical Green AI strategy should begin before an enterprise selects a model or purchases additional computing capacity.
Define the business outcome first. Establish the decision, process, customer experience, or productivity outcome the AI workload needs to improve. Avoid deploying AI simply because a capability is technically possible.
Create an AI workload baseline. Measure request volumes, latency requirements, model utilization, compute consumption, storage, data movement, infrastructure cost, and other available resource indicators.
Choose the smallest effective model. Do not automatically assign every task to the largest available foundation model. Smaller models, specialized models, retrieval techniques, routing, and deterministic automation may satisfy many enterprise requirements.
Optimize prompts, context, and agent workflows. Long prompts, unnecessary context windows, repeated retrieval calls, and uncontrolled multi-agent loops can create avoidable inference workloads.
Modernize the supporting data foundation. Improve data quality, eliminate unnecessary duplication, streamline pipelines, and reduce avoidable movement between platforms. AI efficiency depends heavily on efficient data engineering.
Right-size infrastructure and workload placement. Match workloads with suitable cloud, hybrid, edge, or on-premises infrastructure based on utilization, performance, security, cost, and operational requirements.
Measure efficiency continuously. Track business output relative to requests, compute, infrastructure utilization, latency, and cost. Where reliable energy or emissions data is available, incorporate those measures too.
Govern AI growth as a portfolio. Retire low-value experiments, consolidate overlapping tools, and scale workloads only when measurable outcomes justify continued resource consumption.
IBM’s sustainability guidance similarly emphasizes rightsized models, workload placement, efficient platforms, and infrastructure optimization rather than relying on a single intervention.
The result is an AI operating model that evaluates value and efficiency together.
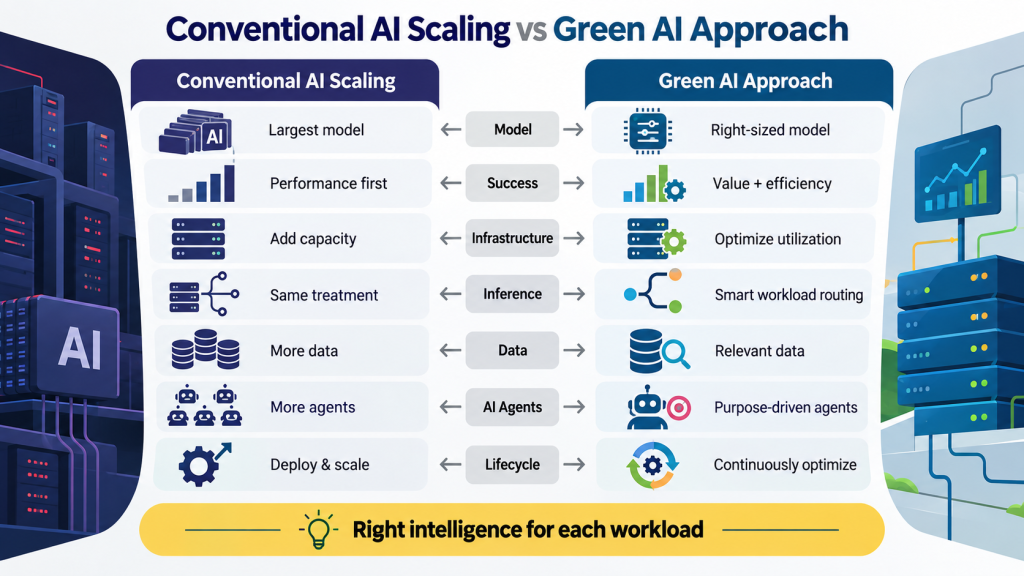
How does Green AI compare with conventional AI scaling?
A Green AI architecture changes what teams optimize for. Accuracy and user experience remain essential, but they are assessed alongside operational efficiency.
What does Green AI look like in a real enterprise use case?
Consider AI-driven demand forecasting in healthcare.
In a 2026 Prolifics engagement, a healthcare distribution organization used AI and machine learning to analyze historical usage and purchasing patterns, predict product demand, determine reorder requirements, and support inventory planning. The solution addressed excess inventory and shortages while helping procurement teams make better decisions.
The project is not presented as a Green AI case study, so no environmental savings should be attributed to it without measurement. It does, however, illustrate where Green AI principles can be introduced into a real enterprise architecture.
A healthcare organization running this type of workload could examine whether every product requires identical forecasting frequency, whether retraining needs to occur continuously, whether historical data can be tiered, and whether smaller models can handle predictable product categories.
High-volatility inventory could receive more frequent AI analysis. Stable categories could run less often. Models could retrain when data drift crosses a defined threshold instead of following an arbitrary schedule.
The organization could then connect model performance with operational measures such as forecast accuracy, infrastructure consumption, processing time, and cost per forecast.
That produces a better question than simply asking whether the company can deploy more AI.
The question becomes whether each additional unit of computing produces enough operational value to justify it.
That is applicable across healthcare, banking, insurance, retail, and public-sector AI deployments.
How should enterprises measure Green AI performance?
Green AI needs measurable governance, or it risks becoming a sustainability statement without operational impact.
Technology leaders should start with metrics their infrastructure can reliably provide rather than inventing carbon figures from incomplete data.
Useful measures can include:
Compute consumed per successful AI transaction.
Infrastructure utilization for AI workloads.
Cost per completed AI business process.
Inference requests by model and workload.
Average tokens processed per transaction.
Model latency relative to compute requirements.
Percentage of requests routed to smaller models.
Training and retraining frequency by model.
Storage and data-transfer requirements.
Energy consumption where measurable and attributable.
These metrics should connect to business KPIs. An AI workload that uses more computing may still be justified if it creates proportionately greater value, reduces another resource-intensive process, or improves a critical outcome.
This is why Green AI belongs within FinOps, MLOps, cloud governance, enterprise architecture, and responsible AI rather than operating as an isolated sustainability program.
Enterprises also need to distinguish efficiency from renewable energy sourcing. Running an inefficient AI workload on lower-carbon electricity does not automatically make the workload efficient. Conversely, an optimized model still has environmental impact if it runs at enormous scale.
Leaders need visibility into both sides: how much infrastructure AI consumes and how efficiently that infrastructure produces useful outcomes.
Conclusion
Green AI gives enterprises a practical way to scale artificial intelligence without treating infrastructure consumption as an unlimited resource. The strongest approach connects model efficiency, modern data architecture, cloud optimization, governance, and measurable business outcomes across the complete AI lifecycle. Prolifics helps enterprises build and operationalize governed AI, modern data platforms, cloud architectures, and AI-ready operating models designed around measurable value and responsible scale. Explore Prolifics AI Services and Prolifics Data & AI Solutions to start evaluating where efficiency should become part of your enterprise AI roadmap.
FAQs
What is Green AI in enterprise technology?
Green AI designs and operates AI systems with computational and environmental efficiency in mind. It reduces unnecessary resource use across models, infrastructure, data, and governance.
How can companies reduce the energy use of generative AI?
Companies can use smaller suitable models, optimize prompts and retrieval, and improve infrastructure utilization. They can also reduce unnecessary model calls, agent activity, and low-value workloads.
Are smaller AI models always more sustainable?
Not always. Sustainability also depends on workload volume, hardware efficiency, retraining needs, data movement, and deployment architecture.
How should CIOs measure the environmental impact of AI?
CIOs should track compute usage, infrastructure utilization, inference volume, training frequency, storage, and data transfer. Reliable energy and emissions data can then be added to AI governance metrics.
Can Green AI reduce enterprise AI costs?
Yes, Green AI practices can reduce waste from idle capacity, oversized infrastructure, and unnecessary model usage. Cost savings should still be validated against performance, efficiency, and business outcomes.
IBM has announced that the Dun & Bradstreet Commercial Graph™ is now available through a Model Context Protocol (MCP) server in the IBM watsonx Orchestrate Agent Catalog. The integration gives enterprises a more secure and standardised way to connect AI agents with verified commercial information and automate business-critical workflows.
As organisations move agentic AI from pilot projects into production, access to accurate and current information has become essential. Agents working with fragmented, incomplete or outdated data can generate unreliable results, particularly in areas such as credit assessment, procurement, regulatory compliance and supplier risk management.
The new integration addresses this challenge by connecting AI agents to Dun & Bradstreet’s trusted business identities and commercial context. Anchored by the D U N S® Number, the D&B Commercial Graph helps agents recognise the same verified organisation across multiple systems and records.
Connecting AI Agents Through MCP
Through the MCP server, organisations can enable agents to discover, retrieve and analyse Dun & Bradstreet’s commercial intelligence within watsonx Orchestrate.
MCP provides a standard, vendor-neutral method for connecting AI systems to external data and tools. It can reduce dependence on custom connectors that take considerable time to develop, secure and maintain.
IBM states that the D&B MCP server can be obtained directly from the Agent Catalog, potentially reducing agent-to-data integration timelines from months to days. Watsonx Orchestrate provides the central environment for building, monitoring, governing and scaling agents across cloud and on-premises systems.
Security and governance are built into the integration. Agents accessing the Commercial Graph operate within Dun & Bradstreet’s established data-quality, permission and audit frameworks, helping businesses align agent activity with their internal security and compliance policies.
Accelerating Adoption Through the IBM–Prolifics Partnership
As an established IBM Business Partner with recognised proficiency in watsonx Orchestrate, Prolifics can help organisations translate this new capability into production-ready business solutions.
Prolifics combines expertise in AI, data engineering, integration, automation and governance to help businesses assess suitable agentic AI use cases, connect watsonx Orchestrate with existing enterprise applications and establish the controls required for responsible deployment.
For example, Prolifics can help procurement teams design agents that monitor supplier stability, sales teams automate prospect research and risk professionals accelerate company verification. Its implementation and integration expertise can also help organisations embed D&B intelligence into end-to-end workflows rather than deploying AI agents as isolated tools.
Prolifics’ wider collaboration with IBM demonstrates its ability to turn IBM technologies into measurable business outcomes. In 2025, it received an IBM Partner Plus Award for North America in the Sustainability category for an AI-powered quality-control solution developed with IBM.
From Business Data to Confident Decisions
The D&B and IBM integration creates opportunities across sales, finance, procurement, compliance and operations. With implementation support from partners such as Prolifics, enterprises can build agents that securely apply trusted commercial context to daily decisions.
The announcement represents an important step towards practical enterprise agentic AI—combining authoritative data, open connectivity, centralised orchestration and experienced implementation support.
It provides verified business identities and commercial intelligence that help organisations consistently recognise companies across different systems and records.
2. What is IBM watsonx Orchestrate?
It is an enterprise platform for building, coordinating, monitoring and governing AI agents and automated workflows.
3. What role does MCP play?
Model Context Protocol provides a standardised way for AI agents to connect with external data sources and tools, reducing custom integration requirements.
4. How can Prolifics support implementation?
Prolifics can assist with use-case planning, architecture, data integration, workflow automation, security, governance and deployment using watsonx Orchestrate.
Imagine Monday morning at a warehouse. A multinational facilities manager checks citywide pollution reading, unsure whether it reflects conditions outside. Across town, a startup founder faces the same uncertainty, with fewer resources to investigate. Both need better local information.
AI-powered air quality monitoring offers a practical way to improve that information. Connected sensors collect local observations, while analytical models help correct readings, estimate missing values, and forecast pollution. Research shows that this combination can expand visibility, but success depends on calibration, validation, and responsible interpretation.
At Prolifics, we bring together AI, connected technologies and data engineering to help businesses turn environmental data into actionable insights. We help organizations connect data sources, improve visibility, and make more informed decisions about air quality monitoring.
Why air quality data gaps matter
The World Health Organization estimates that 99% of people worldwide lived in places exceeding its air quality guideline levels in 2019. It also estimates that outdoor air pollution caused 4.2 million premature deaths that year. These figures establish the global scale of the problem, rather than conditions at any individual workplace. WHO air pollution fact sheet.
Monitoring does not offer equal visibility everywhere. NASA reported in 2023 that shortages of reliable ground monitors leave many communities without detailed local information. Its CityAQ initiative addresses this challenge by combining atmospheric modelling with ground observations and machine learning. NASA’s account of CityAQ.
For businesses, air quality data gaps create uncertainty about conditions around facilities, delivery areas and neighboring communities. A regional reading provides context, but teams may need local observations to investigate a specific concern.
The question is therefore practical: what information would help the organization make a better decision?
How connected sensors expand monitoring coverage
IoT air quality monitoring links sensing devices to a platform that collects and organizes their readings. Teams can use the resulting information to examine differences between locations and changes throughout the day.
How do connected sensors measure air pollution?
Connected air quality sensors use different sensing methods for different pollutants. Optical particle sensors estimate particulate concentrations from scattered light. Electrochemical sensors measure certain gases through electrical responses. Teams must select devices according to the pollutants they need to monitor. EPA Air Sensor Guidebook.
Connectivity allows readings to reach a shared system through networks such as Wi-Fi or cellular services. However, communication speed and measurement quality address different needs. A device can transmit an inaccurate reading immediately.
For organizations using IoT sensors for air quality monitoring, deployment should therefore combine appropriate instruments, useful locations, and a clear quality assurance process.
What research reveals about measurement accuracy
Low-cost air quality sensors can extend monitoring networks, but their raw readings may differ substantially from reference instruments.
Calibration can materially improve readings
A 2021 study by EPA researchers analyzed almost 12,000 daily average PM2.5 measurements from Purple Air sensors and reference instruments across 16 US states.
The researchers found that raw sensor readings overestimated PM2.5 concentrations by approximately 40% under the conditions studied. A correction incorporating relative humidity reduced root mean square error from 8 to 3 µg/m³. This metric describes the typical scale of measurement error, with greater weight on larger errors. Barkjohn and colleagues, 2021.
The business lesson is straightforward: assess data quality before expanding the network. Purchasing more devices without checking their performance can multiply uncertainty.
Machine learning needs local validation
A 2024 study in Chandigarh evaluated two PM2.5 sensor types over ten months and compared five machine learning approaches for calibration. The researchers reported substantial improvements after correction and highlighted how humidity and local conditions influence performance. Ravindra and colleagues, 2024.
These findings support using machine learning to improve measurements. They do not establish that one model will perform equally well across every facility, climate, or pollution mixture.
Multinationals should validate performance across locations. Startups should establish dependable results within a focused pilot before scaling.
How AI can close air quality data gaps
AI can address different information problems, but teams should distinguish corrected measurements, estimated missing values and forecasts.
How does AI improve air quality monitoring?
AI can learn relationships between sensor outputs, reference measurements, and environmental conditions. Teams can use those relationships to correct systematic errors and improve interpretation.
However, complexity does not guarantee better results. In the EPA study, more complex multiplicative models did not substantially outperform the selected correction on independent test data. Organizations should compare proposed models against simpler alternatives. Barkjohn and colleagues, 2021.
How can AI estimate missing air quality data?
Models estimate missing values from relationships within available observations, sometimes incorporating weather or nearby measurements. This process, called imputation, can help analysts work with incomplete datasets.
Research also shows why method selection matters. A 2026 study examined missing measurements of PM2.5 chemical components. Its reconstruction method, which incorporated pollution source relationships, outperformed several comparison methods, including a deep learning model, on a two-month dataset. Zhu and colleagues, 2026.
The implication is practical: test whether a method suits the dataset and preserves meaningful patterns. Label estimates clearly, retain original observations, and avoid presenting reconstructed values as direct measurements.
During validation, reserve later observations for testing rather than relying only on random samples. This helps reveal whether a model remains useful over time, when weather, equipment performance and operating conditions may all change.
Can AI anticipate pollution changes?
AI and machine learning for air pollution prediction combine available observations with models to estimate future concentrations.
NASA’s CityAQ project used local monitoring data and machine learning to improve forecasts from the GEOS-CF atmospheric model. NASA reported that Bogotá incorporated CityAQ information into its air quality warning tools. NASA’s CityAQ findings.
For businesses, forecasts can support preparation and investigation. They still require checks against subsequent observations, especially when conditions change.
What the findings mean for businesses
Real-time air quality monitoring creates value when teams connect information to a specific operational question.
Consider a hypothetical logistics company investigating particulate peaks near a loading area. Its team could compare sensor readings with delivery schedules, wind conditions, and nearby background measurements.
If the evidence suggests a relationship with vehicle queues, managers could trial different arrangements and evaluate subsequent readings. This example illustrates a possible application, rather than a documented client outcome.
Air quality data analytics can support that investigation, but correlation alone cannot establish the pollution source. Weather and unrelated activities may also influence results.
For multinational companies, consistent methods can improve comparisons across sites. For startups, a narrower programme can help establish whether monitoring answers a valuable question before further investment.
Neither organization should treat additional data as an outcome by itself.
Building a monitoring programme that delivers value
Research supports a measured approach to improving air quality monitoring coverage: define the decision, validate the measurements, and establish a response.
Start with the question and location
Identify the pollutant, activity, and area of concern. Choose sensor positions that reflect the investigation rather than installation convenience.
The EPA recommends collocation, which involves operating sensors alongside a reference monitor to evaluate their performance. This step helps teams understand the readings before relying on them. EPA collocation guidance.
Establish ownership and quality checks
Give environmental sensor networks an operational owner and a realistic maintenance budget. Include connectivity, calibration, replacement devices, and analysis when assessing total costs.
Use these checks to keep the program focused and accountable.
Compare sensor performance against reference measurements before expanding monitoring coverage.
Distinguish measured readings from estimates across dashboards, reports, and alerts.
Assign clear owners for maintenance, investigations, escalation, and corrective actions.
When introducing connected sensors for real-time pollution monitoring, track data completeness, measurement error, and alert usefulness. Ask whether the information changes decisions or simply adds another dashboard.
Keep a record of model updates and review performance after operational or seasonal changes. For formal reporting, check applicable monitoring requirements before relying on supplemental sensor data. EPA performance guidance distinguishes informational applications from regulatory monitoring. EPA sensor performance guidance.
Conclusion
Research supports combining connected sensors with validated analytics to strengthen air pollution monitoring. Sensors extend local observations, while AI can improve calibration, reconstruct missing information, and support forecasts.
For businesses, the opportunity starts with a defined problem. Build trustworthy measurements, test models under relevant conditions, and give teams responsibility for acting on the findings. That approach turns better visibility into better environmental decisions.
Enterprise data has never been more valuable, or more difficult to manage. Over time, organizations accumulate legacy databases, disconnected applications, departmental data stores, spreadsheets, and multiple cloud environments. Each system may support an important business function, but collectively they create a fragmented landscape where data is difficult to access, reconcile, govern, and analyze.
The result is a widening gap between the data an enterprise owns and the value it can generate from it.
Enterprise data transformation closes that gap. It modernizes how data is collected, integrated, governed, processed, and consumed, creating a trusted foundation for real-time analytics, intelligent automation, generative AI, and faster decision-making.
However, successful transformation requires more than migrating information from legacy systems to the cloud. It demands a coordinated strategy connecting technology modernization with governance, operating models, business priorities, and measurable outcomes.
Why Legacy Data Environments Limit Business Growth
Legacy platforms often contain decades of valuable operational and customer information. The problem is not necessarily the data itself, it is the architecture surrounding it.
Different departments may use different definitions for the same customer, product, supplier, or transaction. Batch-based pipelines can delay reports by hours or days. Manual data preparation consumes analyst time, while undocumented dependencies make even small platform changes risky.
These limitations create several business challenges:
Inconsistent reporting across departments
Slow access to operational insights
High infrastructure and maintenance costs
Limited scalability for growing data volumes
Complex regulatory and compliance processes
Poor data quality and unclear ownership
Difficulty operationalizing analytics and AI
Dependence on specialized legacy knowledge
A modern analytics dashboard cannot solve these underlying problems. Neither can moving every workload to the cloud without redesigning how data flows through the enterprise.
The goal of transformation must be to make data trusted, connected, accessible, scalable, and actionable.
What Is Enterprise Data Transformation?
Enterprise data transformation is the strategic modernization of an organization’s data ecosystem. It encompasses architecture, platforms, integration, engineering, quality, governance, analytics, security, and organizational adoption.
Unlike a standalone migration project, data transformation considers the complete data lifecycle, from the moment information is created to the point where it supports a decision, customer interaction, automated workflow, or AI model.
A modern data ecosystem may combine cloud data warehouses, data lakes, lakehouse architectures, streaming technologies, APIs, business intelligence platforms, machine learning services, and governance solutions.
The right architecture depends on the organization’s objectives. What matters is that the components work together to deliver consistent, secure, and reusable data.
As the referenced discussion on enterprise data transformation emphasizes, modernization becomes sustainable when platforms, governance, analytics adoption, and operating models evolve together.
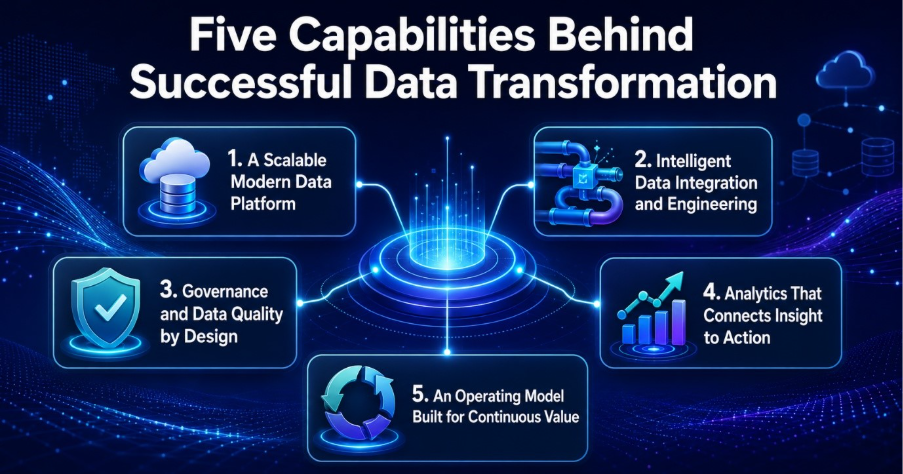
Five Capabilities Behind Successful Data Transformation
1. A Scalable Modern Data Platform
Modern cloud and hybrid data platforms allow enterprises to process larger and more diverse datasets without the limitations of traditional infrastructure.
Cloud-native warehouses and lakehouse architectures can separate storage from computing resources, enabling organizations to scale workloads based on demand. They can also support structured, semi-structured, and unstructured data for reporting, advanced analytics, and AI.
But platform selection should follow business requirements—not industry trends. Organizations must consider workload performance, security, interoperability, data residency, cost, and existing technology investments before choosing an architecture.
2. Intelligent Data Integration and Engineering
Modern analytics depends on reliable data movement.
Automated pipelines can ingest information from enterprise applications, databases, connected devices, partner ecosystems, and external sources. Batch processing may remain appropriate for some use cases, while streaming integration supports scenarios requiring immediate insight.
Data engineering also includes transformation, validation, orchestration, lineage, observability, and exception management. These capabilities reduce manual work and help ensure that analytics teams receive timely, usable information.
Reusable pipelines and metadata-driven automation can further accelerate migration while improving consistency across domains.
3. Governance and Data Quality by Design
Governance should begin at the start of transformation, not after the new platform is deployed.
A strong governance framework establishes who owns data, who can access it, how quality is measured, where information originated, and how it may be used. Catalogs, lineage, business glossaries, policy automation, and quality monitoring translate governance principles into daily operations.
This foundation becomes even more important when data is used to train or ground AI systems. Inaccurate, biased, poorly documented, or unauthorized data can undermine model performance and introduce regulatory, security, and reputational risks.
Trusted AI begins with trusted data.
4. Analytics That Connects Insight to Action
Modernization creates value only when people use the resulting information.
Self-service business intelligence can give authorized users faster access to consistent metrics. Predictive analytics can identify patterns and anticipate future conditions. Embedded analytics can deliver recommendations directly within the applications and workflows employees already use.
The objective is not simply to produce more dashboards. It is to shorten the distance between an event, an insight, a decision, and an action.
Successful organizations design analytics around specific business outcomes, such as reducing customer churn, improving inventory availability, identifying fraud, optimizing equipment maintenance, or accelerating financial reporting.
5. An Operating Model Built for Continuous Value
Data transformation is not a one-time implementation. Business requirements, regulations, source systems, analytical models, and technology platforms will continue to change.
Organizations therefore need an operating model that supports continuous improvement. Central platform teams can provide common standards and services, while domain teams take responsibility for the quality and usefulness of their data.
Treating important datasets as products, with owners, users, service expectations, documentation, and quality measures, can improve accountability and reuse.
A Practical Roadmap from Legacy Systems to Modern Analytics
A phased transformation can reduce disruption while producing measurable wins.
The journey should begin with a data maturity assessment covering architecture, applications, integration, quality, governance, skills, costs, and analytics adoption. This establishes a realistic baseline and identifies the highest-value gaps.
Next, organizations should define business outcomes and prioritize use cases. Instead of attempting to modernize everything simultaneously, they can focus on initiatives that demonstrate value and create reusable capabilities.
A typical roadmap includes:
Assess the current data estate and transformation readiness.
Define business outcomes, priorities, and success metrics.
Design the target platform, integration, security, and governance architecture.
Select high-value workloads for phased migration.
Build automated pipelines with validation and observability.
Establish governance, ownership, lineage, and quality controls.
Deliver analytics and AI use cases tied to operational workflows.
Measure adoption, performance, cost, and business impact.
Expand proven capabilities across additional business domains.
This incremental approach allows teams to learn, adjust, and build stakeholder confidence without losing sight of the enterprise-wide strategy.
Avoiding the “Modernized Silo” Problem
One of the greatest transformation risks is recreating legacy complexity on newer technology.
Migrating fragmented datasets without common definitions preserves inconsistency. Moving inefficient pipelines to the cloud preserves technical debt. Deploying a sophisticated analytics platform without user adoption produces an expensive reporting environment with limited impact.
Organizations should avoid measuring success only through technical milestones such as terabytes migrated or systems retired. Business-oriented measures provide a clearer picture, including:
Time required to produce critical reports
Data quality and reconciliation rates
Analytics adoption across business teams
Pipeline reliability and processing performance
Infrastructure and operational costs
Speed of introducing new data products
Time from insight to business action
AI model accuracy, traceability, and scalability
Turning Enterprise Data into an AI-Ready Advantage
Modern analytics and enterprise AI share the same essential requirement: accessible, governed, context-rich data.
When information remains fragmented, AI teams spend significant time finding, cleaning, and reconciling data. When the enterprise has reusable pipelines, consistent metadata, transparent lineage, and clear access policies, teams can develop and scale intelligent solutions more confidently.
This makes data transformation more than an infrastructure program. It becomes an enabler of intelligent operations, personalized experiences, predictive decisions, and responsible AI.
Accelerate Your Data Transformation with Prolifics
Prolifics helps organizations connect data strategy with implementation and measurable business outcomes. Its capabilities span data assessment, data engineering, data management, analytics, MLOps, governance, application modernization, cloud migration, integration, and AI-powered solutions. Prolifics’ Data & AI services are designed to help enterprises transform fragmented information into trusted insights and scalable intelligence.
Whether you are modernizing a legacy warehouse, building a cloud data platform, improving governance, enabling self-service analytics, or preparing enterprise data for generative and agentic AI, Prolifics can help you move from isolated initiatives to a connected transformation roadmap.
Ready to turn your enterprise data into a foundation for analytics and AI success?
Talk to Prolifics’ Data & AI experts to assess your current environment, identify high-value opportunities, and create a practical roadmap for transformation.
How intelligent, continuous and predictive Quality Engineering turns faster delivery into trusted business outcomes
AI can now generate code, tests and releases at machine speed. Confidence still must be engineered.
Quality is becoming the control layer for digital trust
AI is changing the economics of software delivery. Coding assistants and autonomous agents can interpret requirements, assemble features and propose changes in minutes. Cloud-native applications evolve continuously, data moves across platforms, and releases increasingly combine deterministic software with probabilistic AI behaviour.
This acceleration creates a new constraint. The enterprise may be able to build more change per sprint, but it still needs credible evidence that the change is safe, useful, resilient and ready. When validation capacity cannot keep pace with development capacity, Quality Engineering becomes both the bottleneck and the safeguard.
The answer is not to automate every test. It is to shorten the path from change to a trustworthy decision. That requires Quality Engineering to move beyond a downstream testing phase and become an operating capability spanning planning, build, validation, release and production.
The confidence gap in AI-accelerated delivery
AI-generated code can compile successfully while embedding an insecure pattern, a misunderstood business rule or a subtle integration failure. It can increase the volume of plausible defects at the same time that traditional regression suites struggle with design latency, brittle automation, constrained test data and fragmented reporting.
The defining question is therefore no longer whether AI belongs in software delivery. It is whether the enterprise can independently verify what AI creates, how embedded AI behaves and what risk autonomous systems introduce before a change reaches customers.
A responsible control model separates creation from evaluation. The generator cannot be the only judge of its own output. Prompts, supplied context, generated artifacts, human edits and approvals should be traceable. Before merge, risk-based functional, API, contract, security, accessibility and mutation tests should challenge both the implementation and the original intent.
Human judgment remains essential
The winning model is collaboration, not replacement. AI can generate variants, analyse change, maintain assets and detect patterns across evidence volumes that people cannot review manually. People remain accountable for business intent, risk tolerance, ethics, domain nuance, exceptions and the final release decision.
This Human + AI model expands coverage and feedback speed without surrendering accountability. Review thresholds should reflect risk: low-impact maintenance can be highly automated, while material changes and irreversible actions require explicit human authority.
Build one continuous confidence loop
Quality should be designed into the value stream. Each lifecycle stage should produce evidence for the next decision, while production signals should improve the next cycle of planning and validation.
Lifecycle stage
Quality action
Evidence produced
Plan
Translate critical journeys and business risks into measurable acceptance criteria
Risk tolerances, controls and testable outcomes
Build
Apply standards, code-level checks, API contracts and early automation
Traceable change and early defect signals
Validate
Prioritize by risk and test software, data, performance, security and AI
Coverage, findings and residual uncertainty
Release
Connect transparent, automated quality gates to CI/CD
A defensible release decision and governed exceptions
Operate
Feed reliability, experience and incident signals back into engineering
Continuous learning and recalibrated risk models
This loop changes the role of metrics. Test counts alone cannot tell leaders whether a release is safe. Useful measures connect engineering activity to flow, effectiveness, customer experience, trust and economics.
Flow: lead time for change, test-cycle duration, feedback latency and release frequency.
Effectiveness: escaped defects, defect-removal efficiency, flaky-test rate and automation health.
Experience: critical-journey success, accessibility, performance and customer impact.
Trust: data integrity, privacy controls, compliance evidence and AI quality.
Economics: cost of quality, maintenance effort, environment utilization, reuse and avoided loss.
Test automation and AI testing are different disciplines
Conventional test automation validates predictable interfaces, rules, APIs, data flows and end-to-end processes. AI testing evaluates variable behaviour and asks whether model outputs remain grounded, relevant, safe, robust and useful across changing contexts. Enterprises need both disciplines in one release flow.
For generative AI and retrieval-augmented generation, teams need governed evaluation datasets, model and prompt comparisons, retrieval checks, red-team scenarios, statistical measures and expert adjudication. The evidence should cover relevance, accuracy, faithfulness, context precision and recall, consistency, contradiction, hallucination risk, bias, sensitive-information exposure, latency and cost.
Responsible implementation also requires intended use, prohibited behaviour, thresholds, lineage, monitoring and escalation to be documented. Prompts, datasets, models, retrieval configurations, guardrails and results should be versioned so teams can compare changes rather than evaluate each release in isolation.
Agentic systems must be tested as workflows
An AI agent is not just a model response. It plans, retrieves data, calls tools, maintains state and acts. Quality must therefore cover the complete path from user intent to final outcome.
Goal quality: does the agent achieve the intended business outcome across realistic scenarios?
Process quality: are plans, tool choices, parameters, memory and handoffs correct and efficient?
Safety and control: does it respect permissions, data boundaries, approval points and escalation rules?
Resilience: can it recover from unavailable tools, incomplete context, partial failures and adversarial input?
Governance: are traces, evaluations, approvals and production monitoring reproducible and audit-ready?
Autonomy should expand only as confidence and observability improve. Agents may plan and execute approved low-risk activities, but uncertainty, policy exceptions and high-impact failures should route to people. Learning should come from confirmed outcomes, not unreviewed assumptions.
Predictive Quality directs attention before defects are committed
As regression estates grow, executing everything on every change becomes slow and economically unsustainable. Predictive Quality combines commit differences, requirements, service dependencies, defect history, test health, ownership, complexity and production telemetry to identify where failure is most likely.
The goal is not an opaque risk score. It is an explainable recommendation for reviewers, test scope, data needs, performance checks and release controls. Human override, drift monitoring and outcome-based calibration keep the model accountable. When risk is assessed while requirements and code are still changing, remediation is faster and less expensive.
Solve the enterprise constraints around testing
AI-enabled testing cannot succeed on generation alone. The broader quality system must remove the operational constraints that delay evidence.
Enterprise constraint
Modern QE response
Business value
Unsafe or unavailable test data
Discover sensitive fields; mask, tokenize or synthesize; provision context-preserved subsets through repeatable services
Faster testing with stronger privacy control
Performance and resilience risk
Model peak business events, dependencies, saturation, failure and recovery against service objectives
Protection of revenue, productivity and continuity
Migration and data risk
Reconcile counts, totals, keys, mappings, transformations and referential integrity at scale
Use a federated Testing Center of Excellence to set standards and enable product teams
Comparable evidence without central delivery friction
A federated Testing Center of Excellence makes quality scalable
Enterprise quality cannot depend on isolated specialists or one successful program. A central capability should own standards, reference architecture, reusable assets, governance, metrics and enablement. Product and program teams should apply them in context, while business and control owners define tolerances and govern exceptions. Platform and reliability teams connect environments, observability, resilience and production insight.
The effective TCoE governs the system, not every test. Its value lies in paved roads for automation, test data, metrics and governance: faster adoption, greater consistency, stronger oversight, future-ready skills and a lower total cost of quality.
What measurable transformation looks like
The Quality Engineering CTB includes customer evidence across automation, modernization, test data and operating-model transformation. These examples show why the target is not simply more scripts; it is improved engineering flow and business confidence.
Transformation
Intervention
Reported outcome
Global payments technology leader
LLM-assisted test generation with human review
Coverage increased about 30%; execution accuracy improved from 60% to 80%; automated cases per sprint rose from 55 to 72
Global law firm
Centralized Tosca, Vision AI and NeoLoad automation and performance engineering
Recurring monthly regression fell from 11 days to 8-10 hours; application execution time reductions reached 85-90%; £1 million projected cost avoidance
Global healthcare leader
Enabled SAP subject-matter experts to configure low-code tests
30% reduction in automation effort and 25% reduction in maintenance cost
Mortgage lender
Metrics-driven TCoE with shared methods, risk-based planning and reusable assets
More consistent release-readiness decisions and a scalable foundation for continuous improvement
Reported outcomes should be interpreted in context: realized results are distinct from future projections, and benefit ranges should be validated against each client’s environment, baseline and governance model.
A focused 90-day path from bottleneck to capability
Transformation can begin with one product, migration wave, critical journey or AI use case where slow evidence visibly constrains a business decision. The aim is to prove value through a thin vertical slice while building reusable foundations.
Days 0-30: baseline
Interview product, engineering, business, risk and reliability owners to map critical journeys and decision points.
Select one journey, define tolerances and agree accountable owners and success measures.
Design the minimum architecture, test assets, data services and governance needed for the proof.
Days 31-60: prove
Use a live change to connect requirements, risk-based testing, compliant data, automation and transparent evidence.
Evaluate deterministic software and any AI behaviour with the appropriate mix of assertions, measures and human review.
Integrate the reusable components into delivery rather than running an isolated demonstration.
Days 61-90: scale
Measure cycle time, coverage, accuracy, stability, human overrides and decision outcomes.
Review false positives, escapes and operational feedback, then refine controls and thresholds.
Codify reusable patterns, ownership and exception paths, and approve the next portfolio wave.
The executive outcome should be a working proof, a quantified baseline and an investment roadmap tied to business risk.
How Prolifics connects the quality system
Prolifics approaches quality as a business capability expressed through engineering. Work begins with the outcome an organization needs to protect – revenue, service continuity, regulatory trust, transformation value or customer experience – and works backward into the controls, automation, data, environments and governance required to release confidently.
Quality Fusion. A connected Test Automation and TestOps foundation that brings requirements, planning, automation, defects, CI/CD integration, metrics and release visibility into one quality system.
Agentic Quality Engineering. A Human + AI operating model in which specialized agents support test design, self-healing automation, defect triage, data validation, release readiness and AI governance under explicit controls.
AI TestForge. A structured approach to evaluating generative AI, RAG and agentic solutions across functional quality, groundedness, ethical risk and performance, from individual scenarios to repeatable regression datasets.
TiDium. AI-enabled test-data management for data discovery, masking, context-preserved subsetting, automated provisioning, role-based access and CI/CD integration.
Effecta. High-volume data validation for migrations, transformations, APIs and enterprise platforms, connecting reconciliation evidence from source rules to target outcomes.
The differentiator is not one accelerator in isolation. It is the ability to combine strategy, independent assurance, enterprise integration, data, reusable engineering and accountable delivery around the business journeys that matter most.
Conclusion
AI will continue to increase the speed and volume of change. Whether that acceleration becomes advantage or exposure depends on the quality system surrounding it.
The enterprises best positioned to scale AI will treat quality as a continuous control layer: independent enough to challenge machine-generated change, intelligent enough to focus effort where risk is highest, integrated enough to validate software, data and agents together, and governed enough to keep people accountable for consequential decisions.
Confidence is the product. Quality Engineering is how it is built.
FAQ’s
Why is Quality Engineering important in AI-driven software development?
AI can accelerate software development, but speed alone does not guarantee reliable outcomes. Quality engineering provides independent validation so releases remain safe, resilient, and trustworthy.
How is AI testing different from traditional test automation?
Traditional automation validates predictable applications, APIs, rules, and workflows. AI testing evaluates variable outputs for accuracy, relevance, safety, robustness, and reliability.
What is Predictive Quality?
Predictive Quality uses change data, defect history, dependencies, and telemetry to identify potential risks. It helps teams focus testing where failures are most likely before defects reach production.
How should enterprises test AI agents?
AI agents should be tested across goals, processes, tool usage, permissions, resilience, and governance. High-risk decisions and uncertain outcomes should continue to involve human oversight.
How does Prolifics support modern Quality Engineering?
Prolifics combines Quality Fusion, Agentic Quality Engineering, AI TestForge, TiDium, and Effecta. Together, these capabilities strengthen software, AI, test data, automation, and enterprise quality.